The Memory Leak That Slowly Kills Your Node.js Application
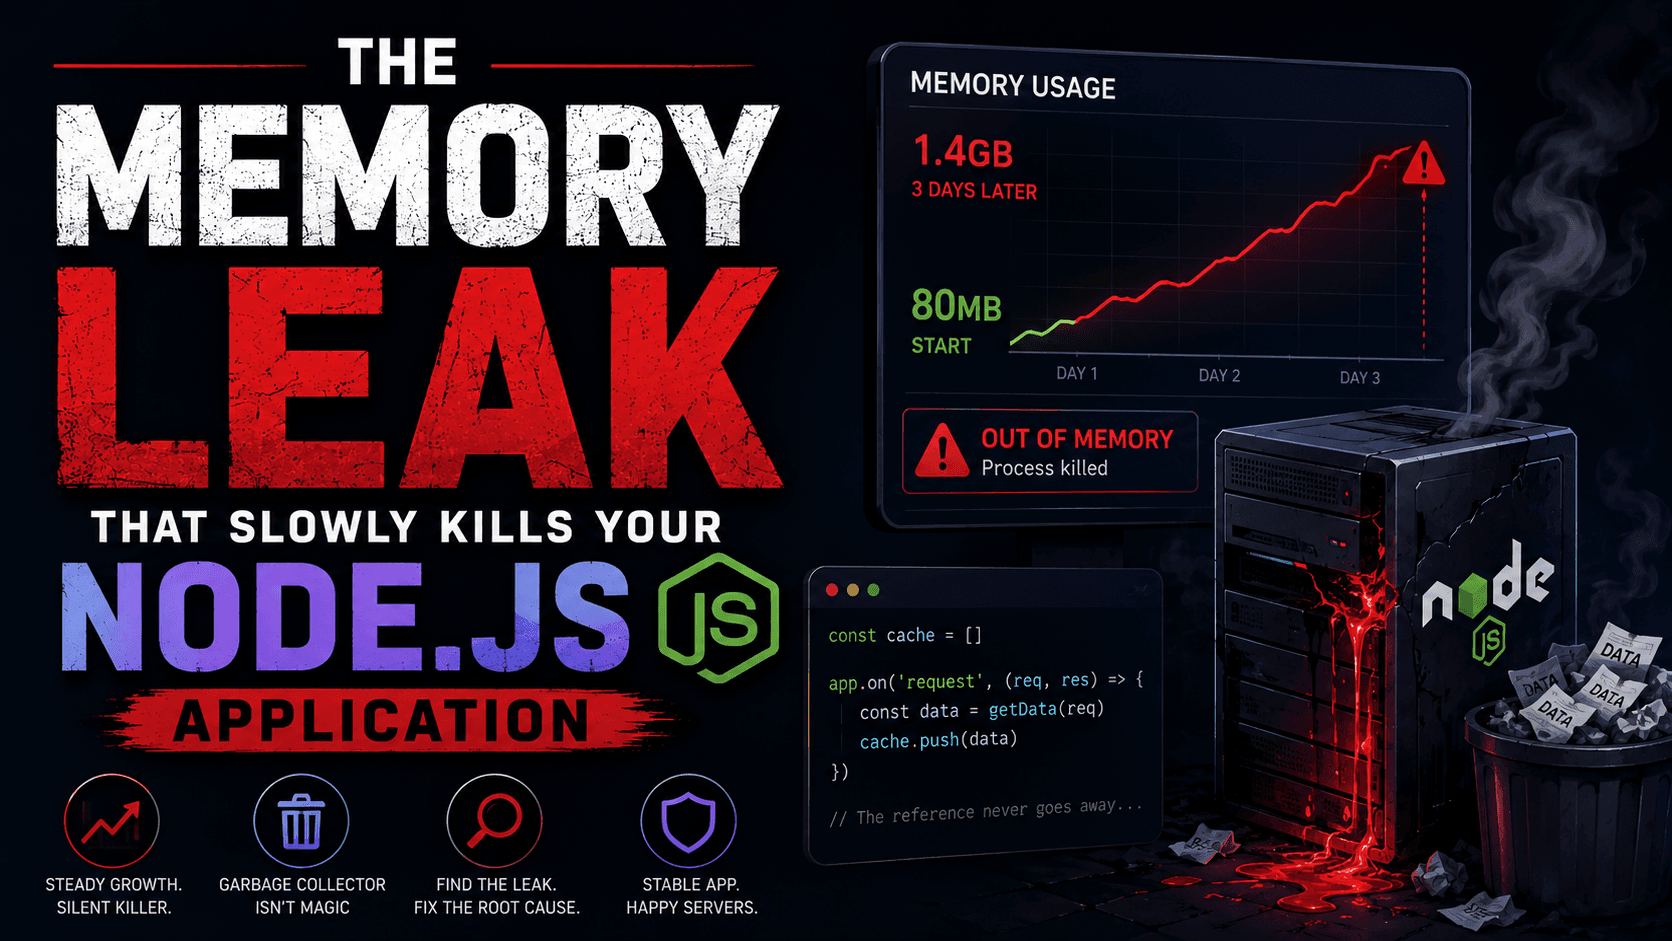
A Node process that runs fine in staging, passes load tests, and then dies in production after eighteen hours isn't hitting a bug in the usual sense. Nothing throws. No stack trace points at a broken function. Instead, heapUsed climbs on a slow, almost imperceptible slope until V8 runs out of room and the process exits with FATAL ERROR: Reached heap limit Allocation failed - JavaScript heap out of memory. The frustrating part is that the code causing it usually looks correct — it just quietly prevents the garbage collector from doing its job, one retained reference at a time.
Garbage Collection Doesn't Mean What It Sounds Like It Means
V8 doesn't scan for "leaked" memory the way a static analyzer would. It only asks one question, repeatedly: is this object still reachable from a root — the global object, an active closure, a live call stack? If yes, it survives. If no, it's collected. A memory leak in a garbage-collected language is never really missing memory management. It's an object that's technically still reachable — through a reference nobody meant to keep — long after the application has stopped caring about it.
That reachability check happens across two generations. New Space holds freshly allocated, short-lived objects and gets swept constantly with a fast copying algorithm called Scavenge. Objects that survive a few of those Scavenge cycles get promoted into Old Space, which V8 only cleans with a slower mark-and-sweep (and periodically mark-and-compact) pass, because scanning the whole old generation on every allocation would tank throughput. Old Space is where leaks actually live — objects that survive multiple GC cycles get promoted there, and V8 only reclaims them during major GC cycles or once heap pressure forces the issue. A leak, structurally, is nothing more than an object that keeps qualifying for promotion into a region V8 is reluctant to scan aggressively.
Node.js Process Memory
├── Heap (V8-managed, garbage collected)
│   ├── New Space   — young generation, swept frequently (Scavenge)
│   ├── Old Space    — long-lived objects, swept rarely (Mark-Sweep)
│   ├── Large Object Space — allocations over ~1MB
│   └── Code Space   — compiled JIT code
├── Stack — call frames, not GC-managed
└── External Memory — Buffers, native add-ons, outside V8's heap entirely
That last box matters more than it looks like it should, and comes back later.
The Four Patterns That Account for Almost Every Node Leak
Unbounded caches are the most common offender, precisely because they don't look like a mistake — they look like a performance optimization. A Map that accumulates one entry per user session, per request URL, or per uploaded file, with no eviction policy and no TTL, is a data structure that by design never releases what it holds. It isn't a bug in the traditional sense; it's a correct cache with a missing exit condition.
Closures over large objects are subtler. A function that captures a big buffer or array in its enclosing scope keeps that entire object alive for as long as the closure itself is reachable — and closures get retained in surprising places: as an Express middleware handler registered once at startup, as a callback passed into a long-lived timer, as an event listener bound at module load. The closure looks tiny in the code; the object graph it's anchoring can be enormous.
Forgotten timers are the most mechanical version of the problem. setInterval without a matching clearInterval keeps its callback — and everything that callback closes over — reachable indefinitely, because the timer itself is a GC root as long as it's active. This is exactly the class of bug WeakRef and FinalizationRegistry exist to guard against in the exact scenario where you'd rather let an object expire than manage its lifetime by hand: most leaks don't start with one dramatic mistake — a timer keeps running after its context is gone, a listener stays attached to something no longer in use, or a closure holds onto an object that no longer matters, and a WeakRef lets you cache that object without preventing it from being collected once nothing else needs it.
The EventEmitter Trap Every Framework Hides
Node's EventEmitter — the base class behind HTTP servers, streams, and most framework request objects — ships with a built-in tripwire for exactly this failure mode. Node.js emits a MaxListenersExceededWarning once the number of listeners attached to a single event on one EventEmitter instance surpasses the default limit of ten, and the warning exists specifically because that pattern is a near-perfect proxy for a leak: something is registering a new listener on every request, every connection, or every loop iteration, without ever calling .removeListener() or .off() on the old one.
The trap is that raising the limit with setMaxListeners() makes the warning disappear without touching the underlying problem — it just moves the threshold where V8 starts noticing. Node.js processes can run for a long time, and when a bug creates a new event listener before cleaning up the old one, or existing listeners are never removed, memory usage grows slowly and eventually causes trouble in production, which is a precise description of what a suppressed warning looks like six weeks later, minus the warning.
heapUsed Isn't the Whole Process — and That's Where Diagnosis Goes Wrong
The instinct when a Node process's memory climbs is to watch process.memoryUsage().heapUsed, because that's the number V8 exposes directly. But heapUsed only accounts for the JavaScript heap V8 manages. heapUsed is V8's tracked JS object memory, rss is the OS-visible total memory of the process including native code, buffers, and stack, and external is C++-bound memory that V8 manages references for — a leak in heapUsed gets fixed with JS-side changes, but a leak in external or rss needs native profiling instead. A process can be leaking Buffers, native TLS socket handles, or file descriptors held open by a streaming library, and heapUsed will look completely flat the entire time, because none of that memory ever entered V8's managed heap in the first place.
Leak pattern
Where it accumulates
Symptom
Fix
Unbounded cache
Old Space (heapUsed)
Slow, linear heapUsed climb correlated with request volume
Add TTL/LRU eviction, or a size cap
Listener accumulation
Old Space (heapUsed)
MaxListenersExceededWarning, closures pile up per-connection
Always pair .on() with .off()/.removeListener() at teardown
Forgotten timers/intervals
Old Space (heapUsed)
Growing count of active handles, closures never released
Store the timer reference, clearInterval on cleanup
Buffer/stream accumulation
External memory (rss, not heapUsed)
rss grows while heapUsed stays flat
Profile native/C++ layer, not the V8 heap snapshot
That last row is the one that sends people down the wrong path most often: they take a heap snapshot, see nothing unusual in the object graph, and conclude the leak isn't real — when it was never going to show up in a heap snapshot to begin with.
Why Raising --max-old-space-size Usually Makes the Real Problem Worse, Not Better
The most common first response to an out-of-memory crash is to increase V8's ceiling with the --max-old-space-size flag, which sets, in megabytes, the maximum size Old Space is allowed to grow to before V8 gives up and crashes the process rather than let the OS run out of memory entirely. That flag has a legitimate use — a workload that genuinely needs more heap than V8's conservative default should get it — but as a response to a leak, it's treating the symptom as the disease. Increasing --max-old-space-size masks memory leaks rather than fixing them, and the right practice is to always profile heap usage first before reaching for the flag.
It also frequently doesn't work at all in containerized deployments, for a reason that has nothing to do with V8. Setting --max-old-space-size=8192 inside a container with only 2GB of memory available does nothing useful, because the kernel's OOM killer terminates the process before V8's own heap limit ever fires — the flag controls when V8 decides to crash the process cleanly with a diagnosable error; it has no relationship to the memory ceiling the container runtime is enforcing from outside. A process tuned against the wrong ceiling gets killed by Docker's own resource-constraints documentation — the mechanism V8's flag has no visibility into — instead of by its own error handler, which turns a diagnosable heap-limit crash into an opaque SIGKILL with no stack trace at all.
Finding the Actual Leak Instead of Guessing at It
The only reliable method is comparative: take a heap snapshot under load, let the process run for a sustained period doing representative work, take a second snapshot, and diff object counts by constructor. Anything whose count grows linearly with request volume and never drops — even after a forced GC — is a candidate. Chrome DevTools' Memory tab, driven through node --inspect, does this comparison natively; Node.js's own inspector documentation covers the workflow for both the built-in inspector and the third-party clinic.js toolchain, which adds flame-graph correlation between CPU and heap growth that the raw inspector doesn't provide on its own.
For leaks specifically caused by unbounded caching, the fix increasingly doesn't require manual eviction logic at all. A WeakRef-backed cache stores a weak reference to each cached value instead of a strong one, and on lookup, checks whether the underlying object has already been collected — if it has, the stale entry is simply removed, which converts "cache that grows forever" into "cache that shrinks automatically under memory pressure," with no TTL bookkeeping required. MDN's WeakRef reference walks through the pattern in more depth, including the caveat that a FinalizationRegistry callback is not guaranteed to run promptly — or, technically, at all — which rules it out for anything time-critical like closing a database connection.
The Takeaway
A Node.js memory leak is never a missing free() call — it's a reference the application forgot it was still holding. The fix is almost never a bigger heap; it's finding which of four patterns — an unbounded cache, a closure over something large, an unremoved listener, or a timer nobody cleared — is keeping an object reachable past the point where the application still needs it. Check rss alongside heapUsed before trusting a heap snapshot that came back clean, because half of that table lives outside V8 entirely.
3Demystifying the Rust Borrow Checker: Fix Lifetime Errors Fast