Mastering Next.js Caching: How to Perfectly Balance ISR, SSR, and Data Revalidation Without Serving Stale Content
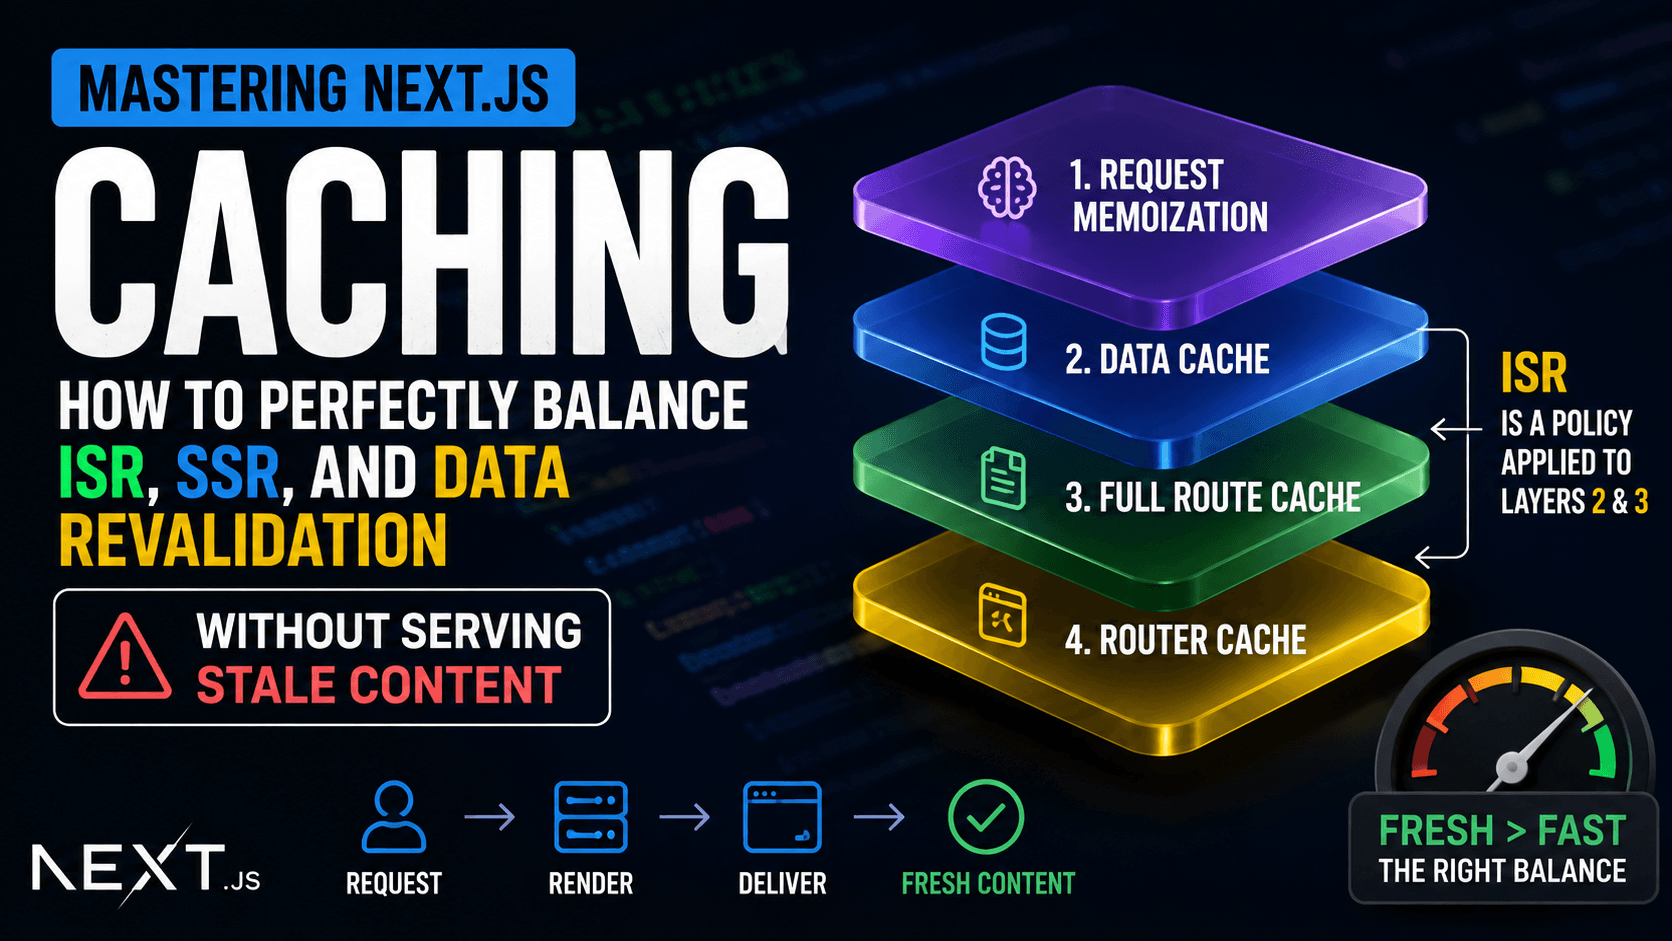
Most stale-content bugs in production Next.js apps aren't caused by a missing revalidate call. They're caused by a mismatch between what a developer thinks a cache boundary does and what it actually does. Next.js runs four distinct caching layers stacked on top of each other — Request Memoization, the Data Cache, the Full Route Cache, and the Router Cache — and Incremental Static Regeneration (ISR) is not a fifth mechanism sitting beside them. It's a policy applied to two of those layers. Understanding that distinction is the difference between a cache strategy that holds up under real traffic and one that quietly serves a pricing page from three deploys ago.
The Four Layers, and Why They Don't Fail Together
The mental model most teams carry over from the Pages Router — "static or server-rendered, pick one" — breaks down in the App Router because caching now happens independently at each of four points in the request lifecycle.
Request Memoization deduplicates identical fetch calls within a single render pass. If three components on the same page call the same API endpoint with identical parameters, Next.js executes that request once and shares the result across all three, but only for the lifetime of that single render — it never persists across requests. This layer is invisible to settings entirely; it resets on every incoming request.
The Data Cache is where fetch results are persisted across requests and deployments, on the server, controlled by cache and next.revalidate options passed to the fetch call itself. This is the layer ISR actually configures. A fetch call with { next: { revalidate: 60 } } writes into the Data Cache with a 60-second time-based invalidation policy — the returned data is reused for any matching request until that window expires, independent of whether the page itself is statically generated.
The Full Route Cache stores the rendered HTML and React Server Component payload for a route at build time (or after a Data Cache miss triggers regeneration), so that static routes can be served without re-executing render logic on every request. This is the layer that determines whether a route is truly static or dynamic at the infrastructure level — and it's downstream of the Data Cache, not a replacement for it.
The Router Cache lives entirely in the client, storing RSC payloads for routes the user has already visited during the current session, so that back/forward navigation and prefetched links don't re-fetch from the server. Next.js's caching guide covers how this layer interacts with the other three. This is almost never the cause of a "stale data in production" bug report — it's the cause of "the data updated but only after I did a hard refresh," which is a materially different problem with a different fix (router.refresh() or a shorter staleTimes config, not a revalidation change).
Request in ──▶ Request Memoization (per-render, resets every request)
──▶ Data Cache (persistent, revalidate: N or 'force-cache')
──▶ Full Route Cache (static HTML + RSC payload, build/ISR)
──▶ Router Cache (client-side, per-session, prefetch-driven)
Treating this as one cache with one knob is the single most common root cause of stale content — a fix applied at the Data Cache layer does nothing to the Router Cache, and vice versa, and most debugging sessions burn time because the symptom (old data on screen) doesn't announce which layer produced it.
What ISR Is Actually Doing Under the Hood
ISR is time-based or on-demand invalidation of the Data Cache, propagated to the Full Route Cache. When a route uses export const revalidate = 3600, every fetch in that route's render tree inherits a one-hour revalidation window unless a specific fetch call overrides it. The mechanic that keeps this from blocking users is stale-while-revalidate: the first request after the window expires still receives the cached HTML immediately, while Next.js triggers a background regeneration; only requests arriving after that regeneration completes get the fresh version. This means a naive mental model — "revalidate: 60 guarantees data no older than 60 seconds" — is wrong. The real guarantee is "data no older than 60 seconds plus however long the background regeneration takes plus however long until the next request arrives to trigger it in the first place." On a low-traffic route, that gap can stretch far beyond the configured window, because regeneration is request-triggered, not a background cron.
On-demand revalidation via revalidatePath() or revalidateTag() sidesteps the timing gap by invalidating the cache at the moment the underlying data actually changes — typically called from a webhook or API route triggered by a CMS publish event or a database write. This is the mechanism that closes the "stale for up to N seconds" window entirely, at the cost of needing an explicit invalidation call wired into every mutation path, which is easy to miss when a data change originates from a source outside the app's own API routes (a direct database migration, an admin panel that bypasses the webhook, a third-party integration writing straight to the DB).
Time-based revalidation vs. on-demand revalidation: time-based trades precision for zero integration work — set a number and forget it, accept a bounded staleness window; on-demand trades integration effort for near-immediate correctness, but only as correct as the coverage of your invalidation calls.
Where SSR Actually Fits — and Why "Force Dynamic" Isn't the Same as Fresh
Setting export const dynamic = 'force-dynamic' on a route opts it out of the Full Route Cache entirely, forcing full server-side execution on every request. This is true SSR in the App Router — no ISR window, no stale-while-revalidate behavior, because there's no cached route to serve while regenerating. The trade-off is direct: every request pays the full render cost, including every uncached fetch inside it.
The nuance that trips up teams migrating from getServerSideProps is that force-dynamic does not disable the Data Cache by itself. A fetch call inside a dynamic route can still specify { next: { revalidate: 300 } }, meaning the route re-renders on every request but the data it fetches is still served from a five-minute-old cache entry unless that individual fetch explicitly sets cache: 'no-store'. This produces a specific, easy-to-miss bug class: a route that appears fully dynamic in the Vercel dashboard's function logs (because it is executing on every request) but is silently reading stale data because one fetch call inside it kept a default caching behavior from an earlier iteration of the code. The fix is to audit fetch options at the call site, not just the route-level dynamic export — the two settings operate on different cache layers and neither one implies the other.
Choosing a Strategy Per Route, Not Per App
The instinct to pick one caching strategy for an entire application is where most of the actual stale-content incidents originate, because different routes within the same app have fundamentally different freshness requirements. A marketing page built from CMS content that publishes a few times a week has almost nothing in common, freshness-wise, with a checkout page reading live inventory counts, yet both often end up under the same blanket revalidate value applied at a layout level.
A more defensible default is to reason about each route by how its data changes, not by how important the route is:
Content that changes on a known publish event (blog posts, marketing pages, docs) — static generation with on-demand revalidation via revalidateTag(), triggered from the CMS webhook. No time-based window needed at all; the page is exactly as fresh as the last publish.
Content that changes continuously but tolerates a short lag (a "trending" list, a dashboard summary) — ISR with a short time-based revalidate (30–120 seconds), accepting the stale-while-revalidate gap as a deliberate trade-off for not hammering the origin API on every request.
Content that must never be stale (checkout, account balances, anything tied to a transaction) — dynamic = 'force-dynamic' paired with cache: 'no-store' on every fetch in that route, accepting the full render-cost penalty as the price of correctness.
Content that's user-specific but not transaction-critical (a personalized "for you" feed) — dynamic rendering for the shell, with fetch calls to any shared, non-personalized data still allowed to hit the Data Cache under its own revalidate window, keeping only the genuinely personalized calls uncached.
This per-route mapping is also where request memoization becomes relevant in practice — a route mixing cached and uncached fetch calls needs to know that memoization only helps within a single render, so restructuring duplicate calls to share a single memoized function matters more on high-traffic dynamic routes than on static ones, where the Full Route Cache already eliminates the redundant work entirely.
The Failure Modes That Actually Show Up in Production
Two patterns account for the majority of real-world stale-content reports, and neither is a Next.js bug — both are configuration mismatches between what a developer set and what they assumed it did.
The first is tag drift: a fetch call tagged with next: { tags: ['products'] }, and a mutation elsewhere in the codebase that calls revalidateTag('product') — singular, missing the 's' — because the tag string was typed by hand in two different files with no shared constant. The cache never invalidates, the bug is invisible in local development (because dev mode disables most caching by default), and it only surfaces in production traffic, often weeks after the mismatched code shipped. The fix isn't a caching change at all — it's exporting tag names as shared constants from a single module instead of inlining string literals at each call site.
The second is layout-level fetches inheriting a stale parent window. A layout.tsx file that fetches shared navigation or user-session data with a long revalidate value affects every route nested beneath it, and because layouts aren't re-evaluated on every navigation the way pages are, a change to that shared data can take far longer to surface than the revalidate number on the page itself would suggest — the page might revalidate every 60 seconds while the layout wrapping it holds a stale session state for an hour. Auditing revalidate settings route-by-route without checking the layout tree above each route is a reliable way to miss this class of bug entirely.
What This Means for a Migration Off getServerSideProps
Teams moving from the Pages Router often map getStaticProps to ISR and getServerSideProps to force-dynamic and stop there, which reproduces the old all-or-nothing model instead of using the layered cache the App Router actually offers. The more accurate migration path treats the old getServerSideProps routes as candidates for the "dynamic shell, cached data" pattern described above — most routes that were fully dynamic under the Pages Router were dynamic because some of their data was live, not because all of it was, and the App Router's per-fetch cache control is precisely the tool for separating those two concerns instead of forcing the entire route into one bucket.
The practical takeaway is that "balancing" ISR, SSR, and revalidation isn't about finding one correct global setting — it's about correctly identifying, per route and per fetch call, which of the four cache layers that data actually needs to pass through, and setting the narrowest possible cache scope that still meets the freshness requirement. Every layer left on its default behavior "just in case" is a layer that can silently diverge from what the rest of the route assumes.
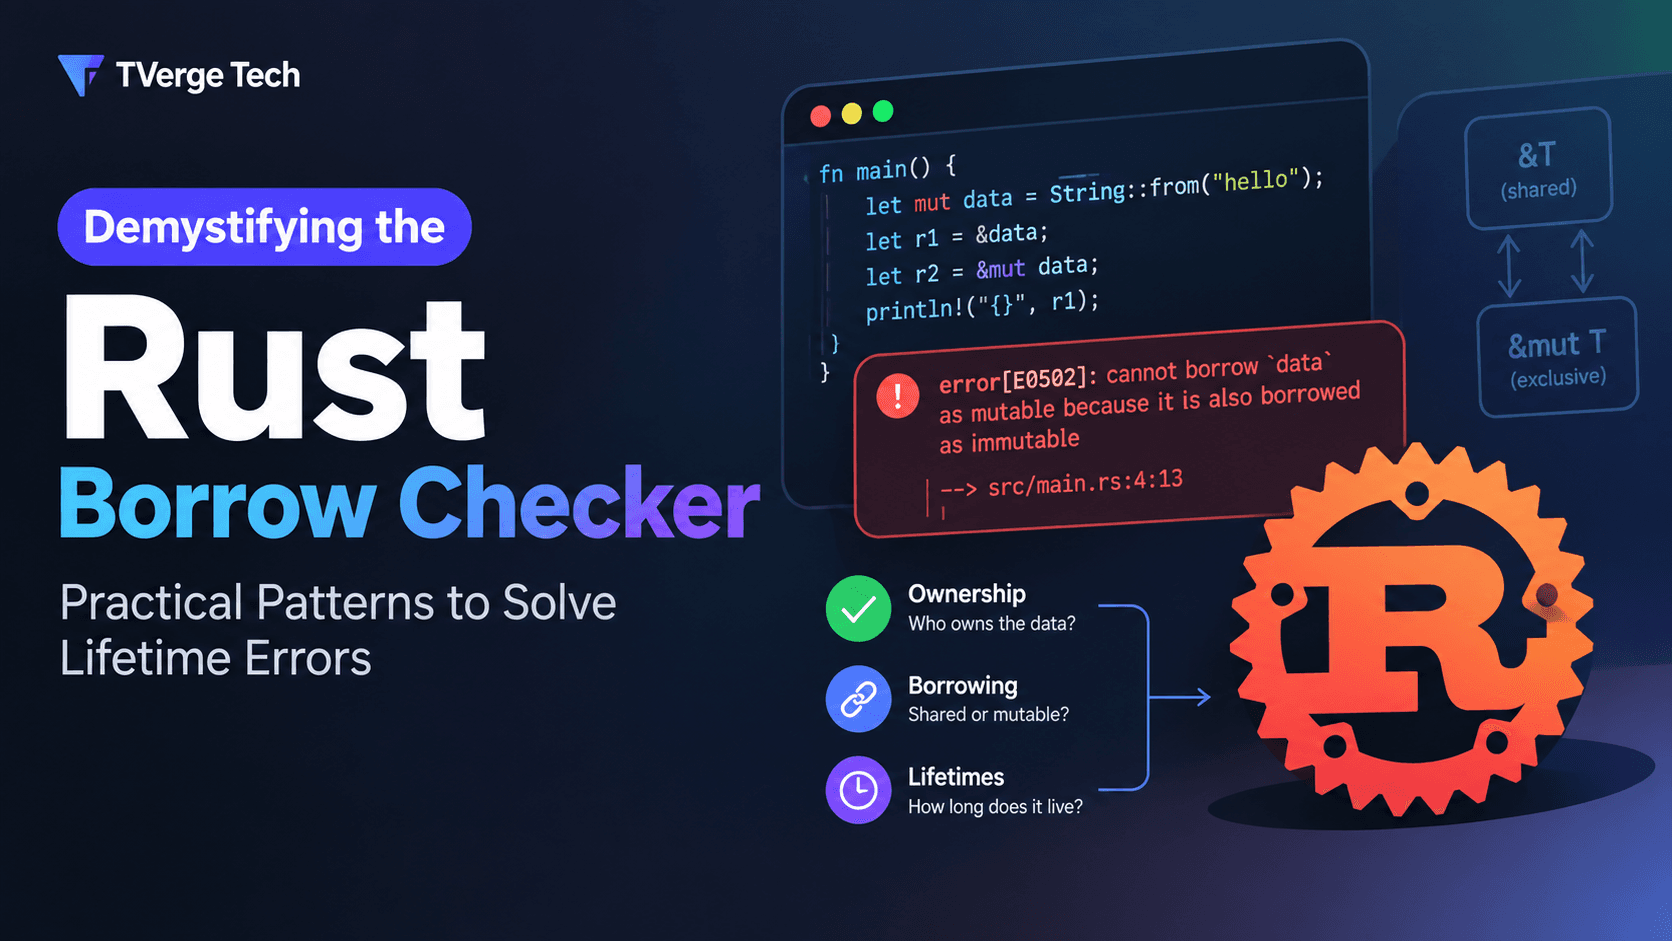
3Demystifying the Rust Borrow Checker: Fix Lifetime Errors Fast